
My previous post on load testing Azure SQL covered the Standard Edition; today I’m moving to the Premium Edition, which is Business Critical in DTU shape.
Again, the calculation mixes CPU, Memory, and disk I/O. The main difference between Standard and Premium is cost. Premium is more expensive and aimed at mission-critical workloads. It has faster storage and built-in replication options. It also includes redundancy, with features designed to keep your solution online.
To make sure you understand the key terms, let me start by explaining them.
Terminology
Tier: the type of database. In Azure, you can choose Standard, Premium, General Purpose, Hyperscale, or Business Critical.
DTU: Database Transaction Units. Azure uses a formula to calculate how many DTUs you can use. This formula is based on CPU cores, Memory, and disk I/O. I haven’t met anyone who can fully explain the formula.
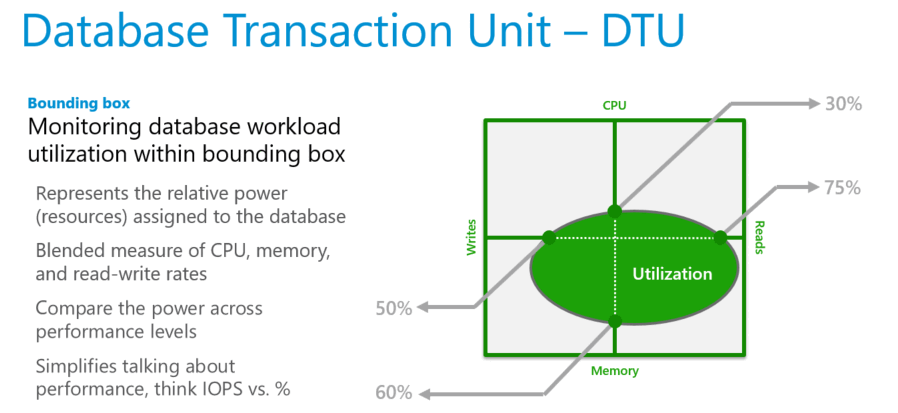
SKU: Stock Keeping Unit. In databases, it’s the number of DTUs or Cores you assign to the database. Database size (GB storage) isn’t part of the SKU, but you can set it separately.
These are the most important terms that keep coming back; let’s move on to the files I’ve used.
The files
I’ve been using a large set of files, and large files within that set. In total, around 500 GB of plain text data. This posed the first problem for the Standard Edition, because the S2 edition has a hard limit on how much data it can hold. This means that the results for this one are somewhat limited. All the other databases I tested could handle the full dataset.
Just loading files into the database doesn’t help; I need to measure things.
The measurements
The testing consists of two measurements. The first part is timing: how long it takes to load all the data into the database. Because I know the data size, I can get a good measure of that database Tier and SKU’s intake capacity. The second measurement is wait statistics. If you want to know what’s holding up your database, these are your go-to metrics. SQL Server does an excellent job telling you what it’s waiting for.
Another result of these measurements is cost. In the table, I’ll show the compute cost. You also need to pay for storage. I’ll add those costs where possible. To calculate the cost, I chose the West Europe region. If you choose another region, prices will be different.
Now, let’s get into the numbers!
The results.
I’ll start with the Customers files: 9 GB of data.
| Tier-SKU | Duration | MB/s | Cost (Euro) |
| P2 | 0:20 | 7,90 | 0,33 |
| P6 | 0:08 | 19,75 | 0,65 |
As you can see, P2 was slower; P6 was much quicker, and even though it cost more per hour, it was cheaper for this specific process. P6 costs twice as much, but is more than twice as fast. Sounds like a good deal to me.
Moving on to the PartSupp files, 46 GB of data.
| Tier-SKU | Duration | MB/s | Cost (Euro) |
| P2 | 1:39 | 7,95 | 1,76 |
| P6 | 0:35 | 22,48 | 2,19 |
The trend seen with the Customers file held true with the PartSupp files. P2 is slower but less expensive. But as prices get closer, the duration gap is growing. P6 is about three times faster, but the price difference is much less. This makes an extra case for P6.
Let’s move to the big files!
| Tier-SKU | Duration | MB/s | Cost (Euro) |
| P2 | 9:02 | 9,54 | 9,90 |
| P6 | 2:37 | 32,94 | 10,97 |
Now, with much more data, you can see the differences even more clearly. Again, P6 is about three times quicker, but the price difference is now only about 10 per cent. The funny thing is that megabytes per second increase more with P6 than with P2. Bigger files or longer loads apparently allow for more speed. My guess is that the DTU is adapting the limits. Bulk inserts shouldn’t need much CPU; therefore, the equation can put more weight on I/O.
Coming back to the storage part. Both the P2 and P6 SKUs include 500 GB of data. This means there’s no extra storage cost. Well, that is until you factor in backup costs. But that’s a whole different rabbit hole I’ve left out of this blog. Way too many options there.
As promised, I also recorded the wait statistics. Here are the top waits for both SKUs.
P2 Waits
| Wait Type | Wait Description | Percentage |
|---|---|---|
| PAGELATCH_EX | Waiting for a page latch in memory (exclusive); this is not a physical disk read. | 38,85 |
| VDI_CLIENT_OTHER | Either spinning up a new replica database or something triggered a database copy (likely the change from S7 to P2) | 15,12 |
| PREEMPTIVE_XE_DISPATCHER | A SQL worker is waiting in a preemptive Extended Events dispatcher operation. | 13,94 |
| POOL_LOG_RATE_GOVERNOR | Internal SQL Server/Azure SQL wait (pool log rate governor) | 9,16 |
| LOG_RATE_GOVERNOR | The transaction log write rate is throttled by the database service tier. | 5,05 |
| XE_LIVE_TARGET_TVF | Waiting while reading an Extended Events live target through its table-valued function. | 3,78 |
| HADR_FABRIC_CALLBACK | Waiting for an Azure SQL high-availability fabric callback. | 3,78 |
| PAGEIOLATCH_SH | Waiting for a data page to be read from storage into memory (shared latch). | 1,63 |
P6 Waits
| Wait Type | Wait Description | Percentage |
|---|---|---|
| VDI_CLIENT_OTHER | Either spinning up a new replica database or something triggered a database copy (likely the change from P2 to P6) | 39,53 |
| PAGELATCH_EX | Waiting for a page latch in memory (exclusive); this is not a physical disk read. | 31,95 |
| PREEMPTIVE_XE_DISPATCHER | A SQL worker is waiting in a preemptive Extended Events dispatcher operation. | 11,10 |
| XE_LIVE_TARGET_TVF | Waiting while reading an Extended Events live target through its table-valued function. | 3,29 |
| HADR_FABRIC_CALLBACK | Waiting for an Azure SQL high-availability fabric callback. | 3,24 |
| PAGEIOLATCH_SH | Waiting for a data page to be read from storage into memory (shared latch). | 2,07 |
| HADR_DB_COMMAND | Waiting on Azure SQL high-availability/fabric coordination (hadr db command). | 1,72 |
| HADR_BACKUP_QUEUE | Waiting on Azure SQL high-availability/fabric coordination (hadr backup queue). | 1,67 |
| LOG_RATE_GOVERNOR | The transaction log write rate is throttled by the database service tier. | 1,39 |
Some surprises here: the VDI wait is much larger than the Standard Tier. I think it’s a combination of switching between SKUs and spinning up replicas. In the end, it’s Business Critical, meaning some form of replica will be available. The P6 log rate is a little over 1%. The biggest contention in this database seems to be access to data pages and writing data (which requires an exclusive lock).
As always, if you want to know more about wait stats, my go-to explanation is the Paul Randall website.
Totals
So, adding it all up, the P2 set me back 11,89. The P6: 13,93. On the other hand, the P2 took 11 hours and 1 minute, whereas the P6 took 3 hours and 10 minutes for the same files. This makes the P6 both cheaper and faster. On the other hand, you pay for the database to be running, so queries are cheaper and faster, but when the database is sleeping for the rest of the time, it can be very expensive. Make sure you understand your workload, the requirements, and budget!
Remember, these are my own tests; run your own when comparing to ensure the simulated workload matches yours. For instance, these tests didn’t include data processing. That will come later.
Comparison with Standard
Let’s round this one up with a comparison between Standard and Premium.
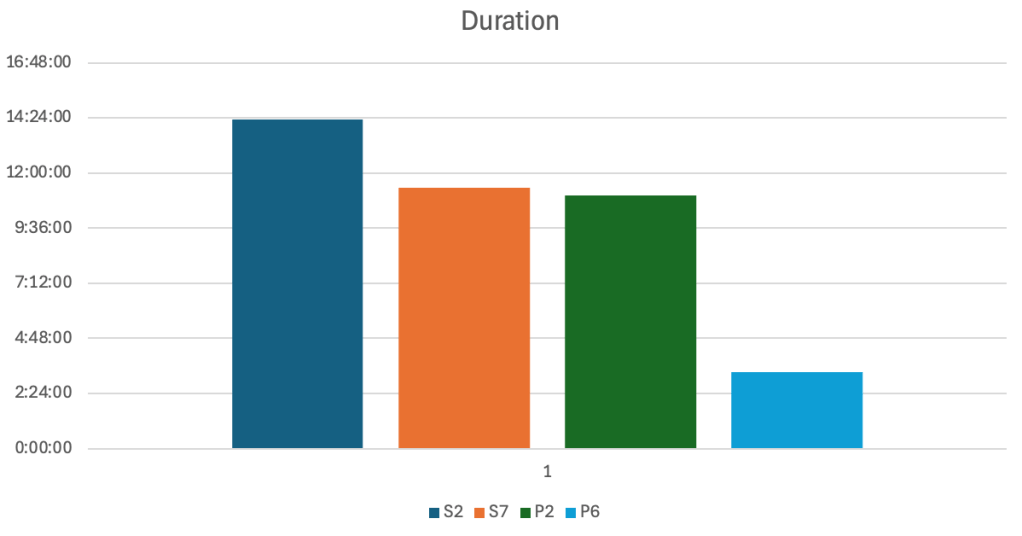
Not much between S7 and P2 in duration, a huge jump when moving to P6 though!
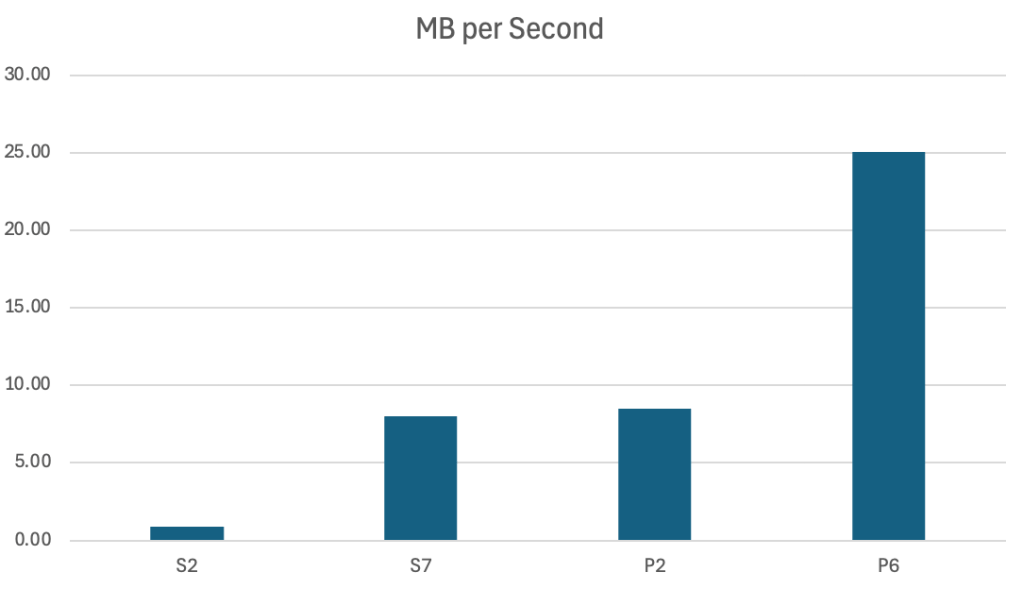
This bar chart shows the difference in average megabytes per second over the three different files. It’s the opposite of duration (which isn’t a surprise), where S7 and P2 are alike, but P6 is racing ahead!
Let’s look at the cost. I’ve included the storage cost, since it’s something to consider as well. I’ve added the database’s monthly cost and the primary storage. With different tiers, you have several extra options to choose from, each adding to your database cost. To keep me sane, I’ve opted not to include those.
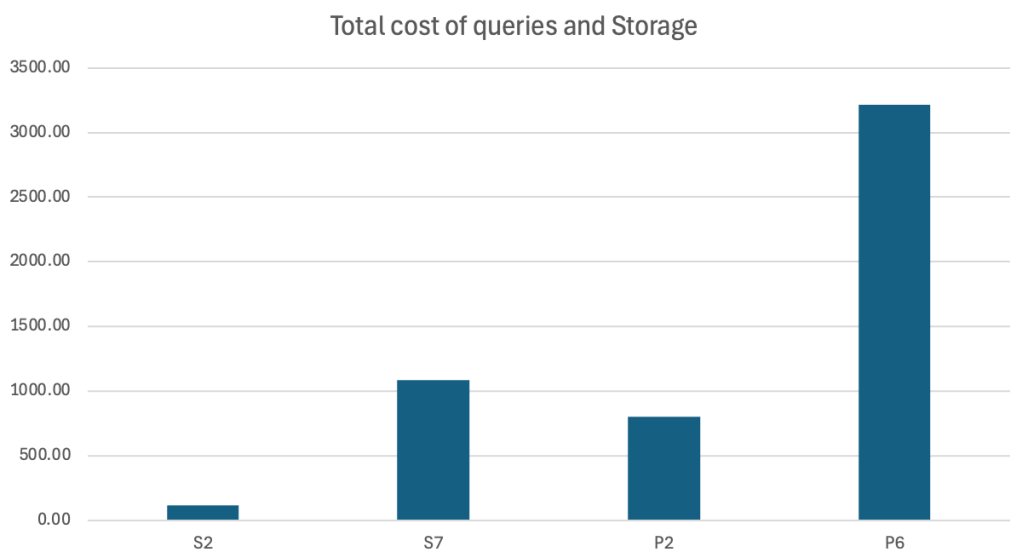
Now, the charts suddenly look very different! P2 is cheaper than S7; P6, with all of its performance, is something you pay for.
In the end, it all comes down to how much you’re willing to pay for performance. And you’ll run a lot more queries than I do to test the database.
Next up in this series: the general-purpose database!

